How to get Google to index my site, in order
Quick answer
Verify the site in Google Search Console on its real domain and submit the sitemap. Run URL Inspection on the pages that matter and click Request Indexing once for each. Link every page in a sentence from a page Google already crawls, and clear any noindex tag, robots rule or stray canonical that URL Inspection names. Google puts the wait at a few days to a few weeks. Neither the Indexing API nor a paid indexing service is a route into Google for a normal page.
Indexing is not ranking. Google indexes a page in three stages: it discovers the address, crawls the page, and decides whether to store it. Only a stored page can appear in a search result, so a page that is not indexed cannot rank for anything. Every step below is free. The first five take between ten minutes and an afternoon, and the sixth is a monthly habit.
The zero-visitor figure at the top of this page comes from The State of Small Business Websites 2026, which breaks it down by platform and industry and puts the median site with search data at an estimated 1 visitor a month from Google search. A zero can mean a site is indexed but ranks for nothing, or that Google has not indexed it at all. The check below tells the two apart.
| Step | What to do | Where | How long |
|---|---|---|---|
1. Verify the site | Add the real domain and prove ownership | Search Console | 15 minutes, then a few days |
2. Submit the sitemap | Paste the sitemap address and confirm Google read it | Search Console, Sitemaps | 10 minutes |
3. Request indexing | Inspect each page that earns money, request once | Search Console, URL Inspection | 20 minutes a day |
4. Link the pages | Link every page in a sentence from an indexed page | The site | An afternoon |
5. Clear the blocks | Remove noindex, robots and canonical blocks | URL Inspection, then the site | An hour, if any turn up |
6. Give Google a reason to return | Faster, fewer, more distinct pages; real outside links | The site and the web around it | Ongoing |
What does Google index mean
Google's index is the store of pages Google has fetched, read and decided to keep. A search looks through that store, not the live web. So a page is indexed when Google holds a stored copy of it, and not indexed when it holds none, whatever the reason.
The three stages fail differently. Discovery is Google learning that the address exists, from a link or a sitemap. Crawling is Googlebot fetching the page. Indexing is the decision to keep it. Ranking comes after all three: an indexed page can sit on page nine for years.
How to check whether Google has indexed a page, and when
Check first, because the answer decides which step matters. If nothing is indexed and Search Console has never been set up, start at step 1. If pages show a reason such as Discovered - currently not indexed, read the status table below. Resubmitting will not change that status. If the pages are indexed and simply rank low, indexing is not the problem. The guide to a website not showing up on Google covers the other reasons.
On a brand-new site, expect the clean case: URL Inspection says URL is not on Google and the reason reads URL is unknown to Google. Nothing is blocking the page, and steps 1 to 3 are the entire fix. The checks, in order:
- A site: search. Type site: followed by the domain into Google, no space, as in site:yourdomain.com. Google lists the pages it has stored from that domain, though the count is approximate. To check a single page, add its path.
- URL Inspection. In Search Console, paste the full page address into the URL Inspection box at the top. A green check beside URL is on Google means the page is indexed. Anything else names the reason, and the reason is the diagnosis.
- Last crawl. To find out when a page was indexed, open the Page indexing panel in that same result. Google does not print an indexed-on date. The closest thing is Last crawl, the date and time Googlebot last fetched the page.
- The Page indexing report. For the whole site, open the Page indexing report in the left menu. It puts the count of indexed pages at the top and, below it, every page that is not indexed, grouped by reason.
Step 1: Add the domain to Search Console as a Domain property (15 minutes)
Search Console is Google's own report on the site: which pages it has indexed, which it has seen and skipped, and why. The sitemap submission and the indexing requests both happen inside it, so this step comes first. It is free and needs only a Google account. If the site has no domain of its own yet, the guide to getting a website on Google covers that first.
- Open Search Console, choose Add property, and pick Domain. A Domain property covers the root, the www version, http and https in one place.
- Verify the real domain, not a builder's preview address, because a property set up on a preview has to be redone once the domain is live. On a Theo site the owner refines the preview in chat, publishes it, then connects their own domain. When that domain is active, the owner signs in with Google once, and Theo sets up Analytics and Search Console for it.
- Prove ownership. The screen shows a record to add at the registrar and names its type. Add it as a new record, check that it shows in the record list, and click Verify. If Google cannot find it yet, the google-site-verification guide has a free check that shows in seconds whether the record is visible, and the slips that keep Google from seeing it.
- Then leave it alone for a few days. The Page indexing report stays empty for a new property until Google has looked.
Step 2: Submit a sitemap, and keep its dates honest (10 minutes)
A sitemap is a plain list of every page address on the site, with the date each page last changed. Google's help page on asking for a recrawl names the sitemap as the method for many pages at once. The same page says a sitemap is useful after a launch or a site move. Most builders generate the file, so the owner's job is to submit it and keep it truthful.
- Find the sitemap address, usually /sitemap.xml on the domain, and open it in a browser. It should list real page addresses, each one the version the site actually uses, with no test pages and no deleted pages.
- In Search Console, open Sitemaps in the left menu, paste the address, and click Submit. The report shows the status (Success, Has errors, or Couldn't fetch), the date Google last read it, and how many addresses it found.
- Keep the last-modified dates true. Google uses them only while they are consistently accurate, so stamping the same date on every page teaches it to ignore them. Google ignores the priority and change-frequency fields altogether.
- Keep one address per page. If a page also loads with a trailing slash, with .html, or under www, redirect every extra version to the one in the sitemap. The post on www versus non-www explains how to pick one.
- Resubmit only after real changes: a batch of new pages, a set of rewritten ones, a move to a new domain.
Step 3: Request indexing once per page in URL Inspection (20 minutes a day)
URL Inspection has a Request Indexing button that asks Google to put one page in the crawl queue. Google describes it as the method for a few pages, available to an owner or full user of the property. Google also sets a quota for submitting individual URLs but does not publish the number. A request is a nudge, not an order.
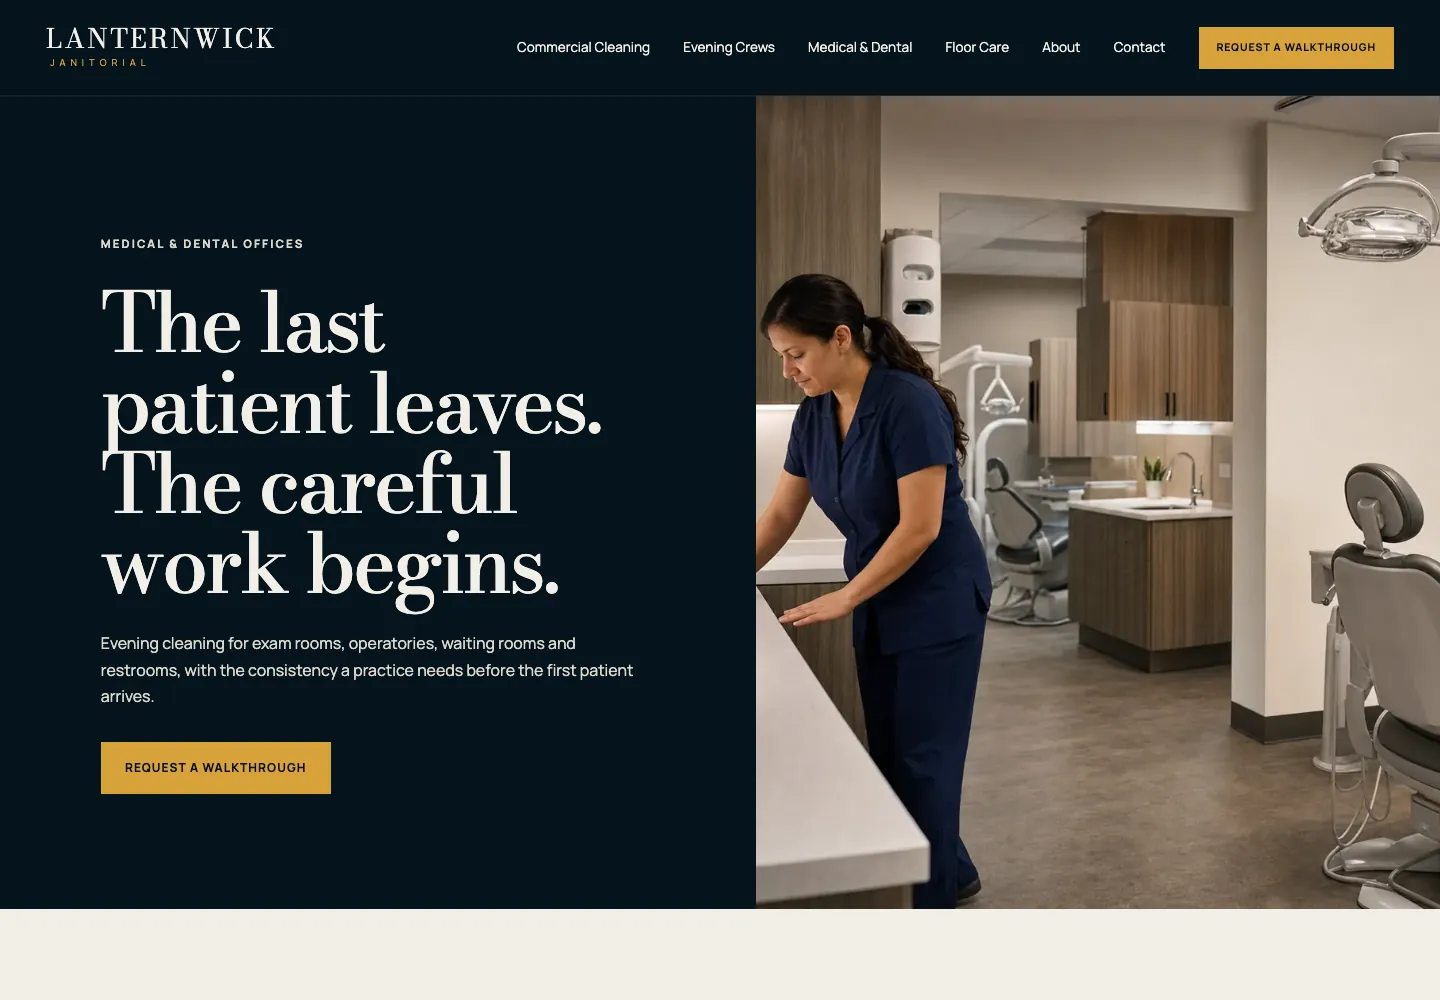
Take Lanternwick Janitorial, a commercial cleaning site Theo built for Omaha. It has ten pages: the homepage, four service pages (commercial cleaning, evening crews with keys and alarm codes, medical and dental offices, floor care), a walkthrough request page, about, contact, and the privacy and terms pages. The table puts them in the order to request, and the medical and dental page, one of the first to request, is pictured below. See the live site.
- List the pages that earn money or answer a customer's question, in priority order: the homepage, each service page, the service-area page, contact, about, then the strongest posts.
- Inspect the first one, wait for the verdict, then click Request Indexing. Work down the list until Search Console reports the quota is reached, and pick up the next day where it stopped.
- Request each page once. Google's guidance is that requesting a recrawl of the same URL several times will not get it crawled any faster. The same guidance says a request does not mean the page will be included in search results at all.
- Write down the date. The crawl can take weeks, so give it a full week before reading the report. Last crawl is the first thing that changes.
| Order | Pages to request (Lanternwick Janitorial) | Why these |
|---|---|---|
First | The homepage, titled Nightly Commercial Cleaning in Omaha; the four service pages; the walkthrough request page | The pages a building manager lands on from a search, and the page that turns a visit into a walkthrough |
Next | About, contact | The page that says who runs the company and its night crews, and the page with the address, phone, hours and towns served |
Never | Privacy notice, terms of use | Google reaches them through links if it wants them |
Step 4: Link every page from a page already in the index (an afternoon)
Google decides what to crawl by predicted value. On a small site, the strongest everyday signal of value is a link from a page Google already visits. A page with no links pointing at it, or only a footer link, reads as unimportant. An indexing request asks for one crawl. A link keeps sending Googlebot to the page each time it revisits the linking page.
- Link from the homepage copy, in a sentence, to each service and location page: the line about water heaters links to the water heater page. A footer list of every page is boilerplate. A link inside the text of a related page carries more meaning.
- Keep every page within three clicks of the homepage, and link each new page from two or three related pages already in the index, with a link back.
- Use the page's own words in the link. Link text such as "water heater repair in Mesa" tells Google what the page is before it fetches it. "Click here" tells it nothing.
- Earn a few real links from outside: a supplier's dealer page, a trade association directory, the chamber of commerce, a local news story. Skip link farms and bulk link sellers.
- Make it a monthly job. The SEO maintenance checklist puts an internal-link pass and an indexing check on the monthly list, so a page added in March is not still orphaned in June.
Step 5: Clear the settings that tell Google to stay out (an hour, if any turn up)
URL Inspection names the block when there is one, and the status table below shows how each reads. These are settings a site picks up by accident, usually left over from a builder's staging mode, a redesign or a domain change. Each needs one Request Indexing after the fix.
- Open yourdomain.com/robots.txt in a browser. A line reading Disallow: / beneath User-agent: * tells every crawler to stay out of the whole site. Remove that line, or narrow it to the one folder that should stay private. The Blocked by robots.txt guide lists what each platform blocks on purpose.
- Look for a noindex tag. Builders set it on hidden and draft pages and on a whole site that is still unpublished. A redesign often carries it over. The tag lives in the page's settings or in the code at the top of the page. The Excluded by 'noindex' tag guide shows where the switch is on each platform.
- Check each page's canonical, the address that tells Google which version of a page is the real one. It should point at the page itself. A canonical left pointing at an old domain after a move sends every page's credit away.
- Check the domain itself. A parked or forwarding domain sends Googlebot to the registrar's page instead of the site. Turn off parking and forwarding at the registrar, and point the domain at the site. The registrar's page keeps showing until the records update, usually within a few hours.
Step 6: Speed, fresh pages and a reason to come back (ongoing)
A crawl allowance is earned. Google spends more of it on a domain whose pages respond quickly and get used: linked, visited, and updated with something new. Page speed and fresh content are often listed as indexing steps. Both help, though a fast site with no links still waits.
- Keep pages fast. A server that answers slowly gets fewer fetches per visit, so Googlebot sees less of the site each time. Compressed images, no unused scripts, and a host that serves static pages over HTTPS cover most of it. On a Theo site, page speed is one of the technical items the growth work on Starter and Pro improves.
- Publish fewer, more distinct pages. Twenty service-area pages that differ only by the town name look, from outside, like one page copied twenty times. Five town pages with real detail (the neighborhoods served, the jobs done there, a review from each) give Google something distinct to crawl.
- Add something worth fetching on a steady cadence: a page that answers a question customers ask on the phone, a post about a job, an updated prices page. Each new page linked from an indexed page gives Google a reason to return.
Sharing the site, Google Business Profile and analytics: what each does for indexing
Three more things owners are often told to do: share the site, set up a Google Business Profile, connect analytics. None of them puts a page in the index on its own.
- Sharing the site on social media brings people, not Googlebot. Links in social posts are usually marked so that search engines do not count them. What sharing does is put the site in front of someone who might link to it from a site of their own, and that link is what counts.
- A Google Business Profile does not index the website either, but it puts the business on the map and links to the site from a page Google runs. Theo's step-by-step Boost checklist, part of Starter and Pro, walks owners through Google Business Profile, Apple Business Connect, Bing Places, Yelp and the other listings that matter. Each listing can also carry a link to the homepage.
- Google Analytics tells the owner when visitors begin to arrive, but it does not affect whether Google indexes anything. Connect it once the domain is active. Impressions, which arrive weeks before clicks, show in the Search Console Performance report and not in Analytics.
What the other Page indexing statuses mean
Google's Page indexing report files every page it has not added under a reason. Discovered - currently not indexed, a page Google knows about and has not visited yet, has a guide of its own, with theo.site's own dated checks. When many town or service pages wait at once, read two of them side by side. Google's spam policies describe doorway pages as pages created to rank for specific, similar searches. One example they give is a set of pages targeted at particular towns that funnel visitors to one page. Twenty service pages that differ only by the town name look like that from outside.
The first three statuses in the table match the three stages of indexing. The rest are the blocks from step 5, copies of the same page, and the leftovers of a move or a visit the site did not answer. Owners who got Google's New reasons prevent pages from being indexed email can start at the guide to that email.
| Status in Search Console | What it means | What to do |
|---|---|---|
URL is unknown to Google | Google has never seen the address. | Submit the sitemap, request the page once, and link it from an indexed page. |
Google has the address but has not fetched the page. | One request, then in-copy links from indexed pages, then make the page more distinct from its siblings and wait the few weeks Google allows. | |
Google fetched the page and has not added it for now. | Leave feeds, tag pages and tagged copies. For a page you want found, merge near-duplicates, add detail only you have, and request once. | |
The page itself asks to be left out. | Remove the tag in the page settings, then request once. | |
The robots file forbids the fetch. | Edit the file. A Disallow: / line blocks everything. | |
Google disagrees about which version is real. | Merge the two pages and redirect one to the other, or make them distinct enough to stand alone. | |
The page is a copy and names no main copy, so Google picked one. | Inspect it. If Google kept your real page, leave it. | |
A copy of a page names the main address, and Google shows the main one. | Nothing, unless the copy is a page you want found on its own. | |
The address forwards somewhere else. | Normal after a move. Request the destination, and keep only destinations in the sitemap. | |
The address says the page does not exist. | Fine if the page was removed on purpose. If it moved, forward the old address (301) to the page on the same subject, and take the old one out of the sitemap. | |
The page loads but reads as empty or missing. | Give it real content, or let a page removed on purpose answer Not found (404). A homepage that says only Coming soon reads as a soft 404. | |
The forward from this address never ends on a page that loads. | Point the old address straight at the final page. | |
The site answered Google with a server code instead of the page. | Check that the page loads, then run Test live URL in URL Inspection. | |
The site answered Google's visit with a refusal code in the 400s other than 401, 403 or 404. | Leave background addresses that were never pages. For a real page that opens for you, ask the host to let Google through. |
The two shortcuts that do not work: the Indexing API and paid indexing services
The Google Indexing API sounds like the answer: a way to tell Google about a page directly, with no queue. Google's documentation limits it to pages that carry job posting or live-stream video markup. The same documentation warns that abusing the API may get access revoked, and that Google's spam policies apply to anything submitted through it. A plumber's service page, a restaurant's menu and a law firm's homepage do not qualify. Plugins that push every page through the API rely on a loophole.
Paid indexing services promise any page in Google within days, for a fee. The routes into Google's index are Search Console requests, a sitemap and links, and an owner already has all three for free. IndexNow, the protocol these services tend to cite, is accepted by Bing and some other search engines, but Google does not take part in it. That leaves the way Googlebot has always found pages, by following links from pages it already crawls. The service places a link to the page on a network of pages Googlebot visits often. That can get the page fetched. It cannot get the page kept, which is Google's quality decision.
How long it takes Google to index a site, and when to stop waiting
Google's published range for a crawl after a request is a few days to a few weeks, with no promise that the page will be included at all. Budget six weeks before reading the Page indexing report as a verdict on the whole site. On a Theo site, connecting Google submits the sitemap on every plan, and the technical fixes are part of the growth work on Starter and Pro. On any site, the checks below take ten minutes a week.
A simple test shows which kind of problem the site has. Request indexing for the most important pages over a few days, then look at Last crawl a week later. If most were crawled, the queue was the problem and the rest will follow. If only a few were, Google is declining even on request, and the answer is the site itself: fewer pages, each more distinct, better linked.
| When | What to check | What a good result looks like | Who |
|---|---|---|---|
Day 0 | URL Inspection on the homepage and the three pages that earn the most | Each one indexed or with a named reason, and none of the blocks from step 5 | The owner at launch |
Weekly | Page indexing report: Indexed, Discovered, Crawled but not indexed | Indexed rising and Discovered falling. Discovered falling while Crawled rises means Google fetched and rejected | The owner. On Starter and Pro, Theo's Growth tab shows each fix made and page published, and a weekly email counts the new posts and updates |
Week 4 | Performance report, filtered to searches without the business name | Any impressions at all. They arrive before clicks | The owner |
Week 6 | The whole report against day 0 | If nothing has moved, stop requesting and work on the site: fewer pages, more distinct, more links | The owner, or the search work on Starter and Pro |
What indexing looks like when it works: impressions first, then clicks
Impressions are the first thing to move. A page that has just been indexed starts appearing far down the results for a few searches, counted as impressions long before anyone clicks. So the good news in the Performance report comes in order: impressions, then average position, then clicks. An owner who watches only the click count can miss the first sign that indexing worked.
Buy My Lunch, which takes school lunch orders online, came to Theo in June 2026. In the 90 days to September 27, 2026, as new pages from its growth work went live, its search impressions reached 61,700, up from 7,500 in the 90 days before. Over those two windows its average position improved from 13 to 8, and clicks from Google search went from 131 to 929. Those are the project's own Search Console numbers, shown with the owner's permission.
Mistakes that keep a site out of Google's index
Each of these shows up in Search Console once Google next crawls the page.
- Leaving each page's canonical pointing at the old domain after a move. The credit for every page flows to an address that no longer serves it. Set every canonical to the page itself, then request the homepage once.
- Submitting a sitemap that still lists redirecting or deleted addresses. Google spends the visit collecting Page with redirect and Not found (404) verdicts instead of fetching live pages.
- Publishing a homepage that says only Coming soon. Google fetches it, files it as a Soft 404, and is slow to return for the finished version.
- Moving to a new domain or builder and dropping the old addresses. The pages Google trusted return 404, and the new ones start from zero. Redirect the old addresses that still get traffic to the matching new pages, and read what a move does to rankings before the switch.
Frequently asked questions
How much does it cost to get Google to index my site?
Nothing. Search Console is free, and both the sitemap submission and URL Inspection happen inside it, in your own Google account. On a Theo site, connecting Google submits your sitemap on every plan, so Google finds every new page, and the technical fixes are part of the growth work included in Starter at $69.99 a month (free for the first 30 days) and Pro at $129.99 a month. That work never uses chat credits, which pay for the changes you ask for in chat.
How long does it take Google to index a new website?
Days to weeks. Google says a crawl after a request can take anywhere from a few days to a few weeks. A verified property, a submitted sitemap and one request for each main page are all Google offers to move that along. Even then, a request does not guarantee that Google will index the page. Give the whole site six weeks before judging it.
Who owns the Search Console property and the site if Theo does the indexing work?
You do. The Search Console property lives in your own Google account, so its history stays there whatever happens to the site. The pages, words and photos on the site are yours as well, and Pro adds read-only access to the site's code on GitHub, which you can copy. You can cancel anytime, and the confirmation shows when the plan ends.
How do I index my site on Google if nobody links to it yet?
Submit a sitemap in Search Console and request indexing for each main page in URL Inspection. Those two steps are how Google hears about a site that no other site links to. There is no form and no fee. Then earn one or two real links, because links get a page crawled.
Does requesting indexing again make Google crawl faster?
No. Asking again does not move a page up the queue, and each request uses part of the quota Google sets for individual pages. Request each page once, then add links to it while waiting.
How do I check when a page was indexed?
Paste the address into URL Inspection in Search Console. Google does not show an indexed-on date, but the result shows Last crawl, the date and time Googlebot last fetched the page. If the result reads URL is on Google, the stored copy exists. The Performance report, filtered to that page, shows the first date it earned an impression.
Can I pay to get Google to index my site faster?
Not through any route Google accepts. Google limits the Indexing API to job posting and live-stream video pages, and IndexNow does not reach Google. A paid service can only place links to the page on sites Googlebot visits. At best, that gets the page fetched.
Getting a site indexed on Theo
On a Theo site, the growth work on Starter and Pro covers most of the six steps above. When the domain is active and the owner has signed in with Google, Theo sets up Search Console and submits the site's sitemap on every plan, so Google finds every new page. Theo also fixes the technical issues that keep a page out of the index, improves page speed, and drafts the pages and posts that give Google more worth crawling. Those drafts wait in the Growth tab for the owner's review unless auto-publish is on. All of the work shows there, a weekly email counts the new pages and updates, and none of it uses chat credits. Starter is $69.99 a month, free for the first 30 days, and Pro is $129.99 a month. An owner whose site is already live can check where it stands with Google through the free website audit, which needs no login and reports traffic, rankings, search health and specific fixes.
More like this in the guides and under getting found on Google. The audit numbers quoted across these posts are in Theo's research.